How We Built the Core of Atmet: A Brain That Understands the Company Before AI Works Inside It
How We Built the Core of Atmet: A Brain That Understands the Company Before AI Works Inside It
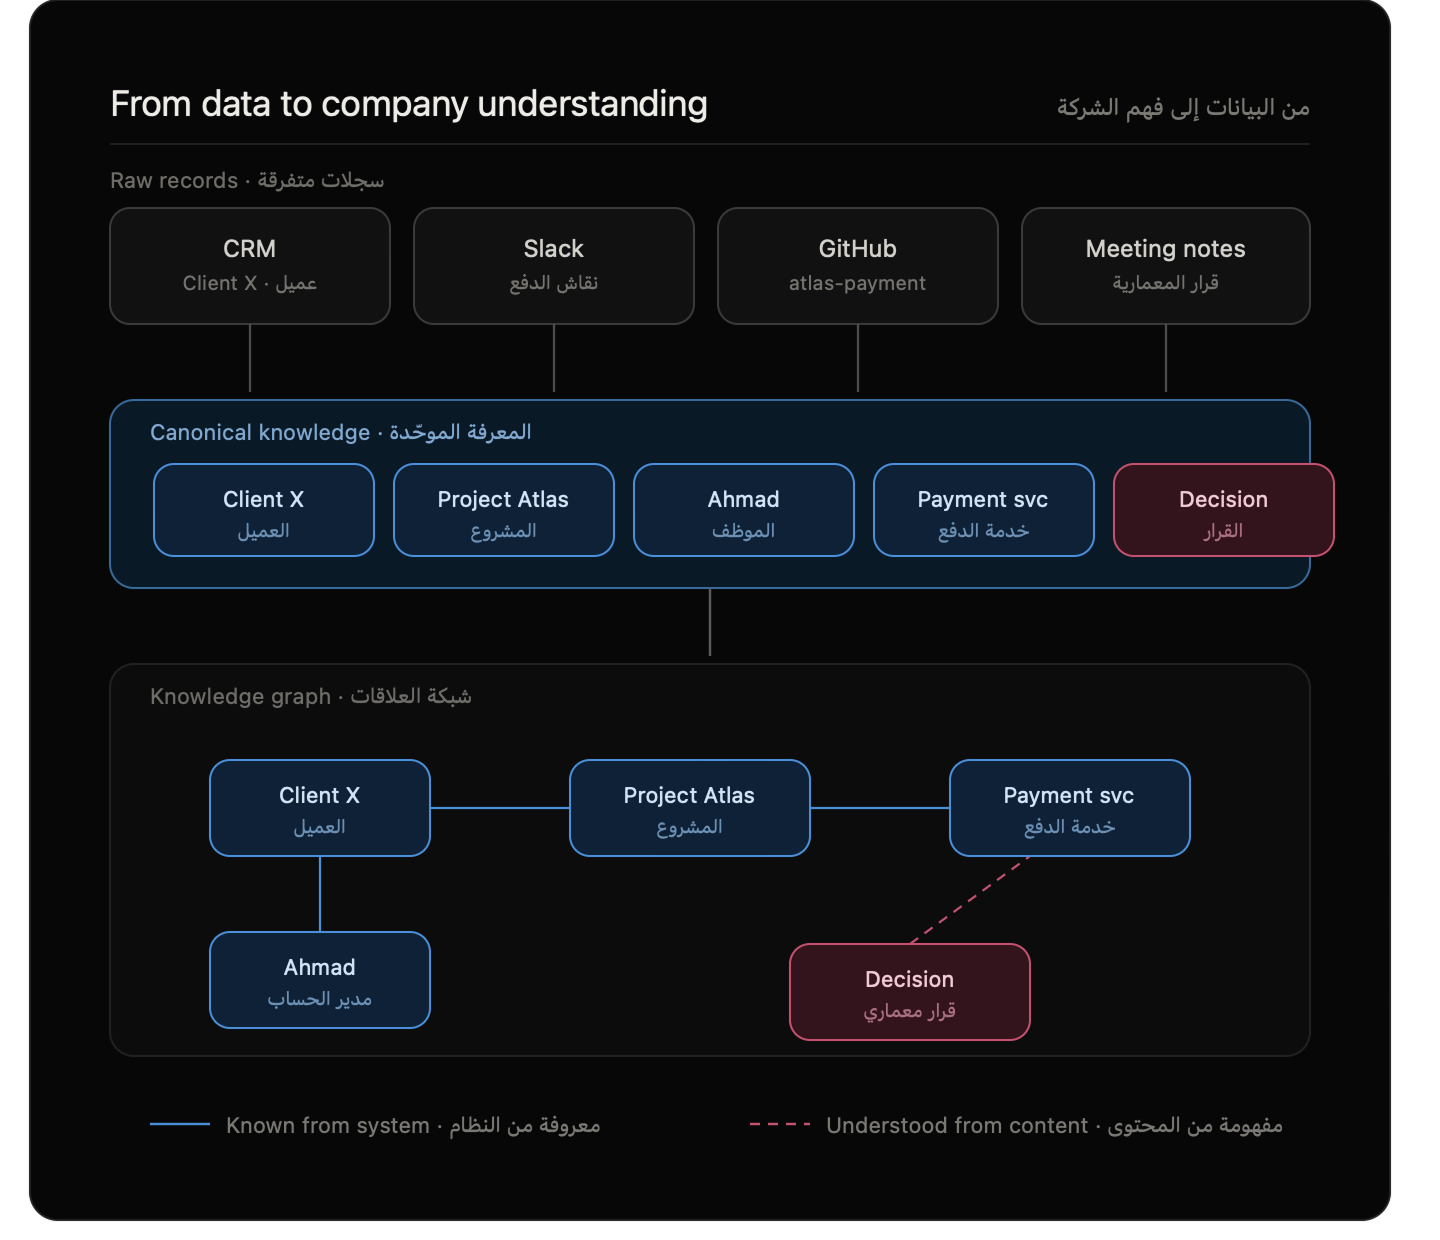
We built Atmet so partners can create AI agents and automate workflows across company departments. The core difference is the knowledge layer: a company brain that lets agents understand work, connect external applications, and take controlled actions without being retaught the business every time.
Atmet was not meant to be only another automation tool like n8n or Zapier with a nicer interface or local model support. We wanted it to become the company brain: a shared foundation for querying knowledge, building agents, and automating work.
When we worked with a client we will call X, the problem was not a lack of information. The company knew a lot, but that knowledge lived across Google Drive, Slack, CRM, project tools, GitHub, databases, Excel files, and internal systems.
We Did Not Want to Move the Company Into Atmet
The obvious knowledge-base idea is to collect everything in one place. In real companies, that is rarely practical. Sales lives in the CRM, engineers live near code in GitHub, decisions happen in Slack, documents live in Drive or Notion, and finance and operations rely on their own systems.
So we took the opposite direction. Atmet should reach knowledge where it already lives. Slack stays Slack, GitHub stays GitHub, CRM stays CRM, but AI can start seeing them as connected parts of one company.
We Quickly Learned That a Vector Database Is Not a Knowledge Base
A basic RAG prototype can chunk documents, create embeddings, store them in a vector database, and send relevant chunks to a model. That is useful, but it is not enough for a living company.
The hard questions came quickly: Which version of a contract is current? Is Project Atlas in Slack the same project in the project-management system? What if the answer is a number in a database? What if the user is not allowed to see the result?
Vector search became one layer in a larger brain: original data, canonical knowledge, metadata, search indexes, a knowledge graph, permissions, versions, and change history.
The Knowledge Layer Needed a Shared Language
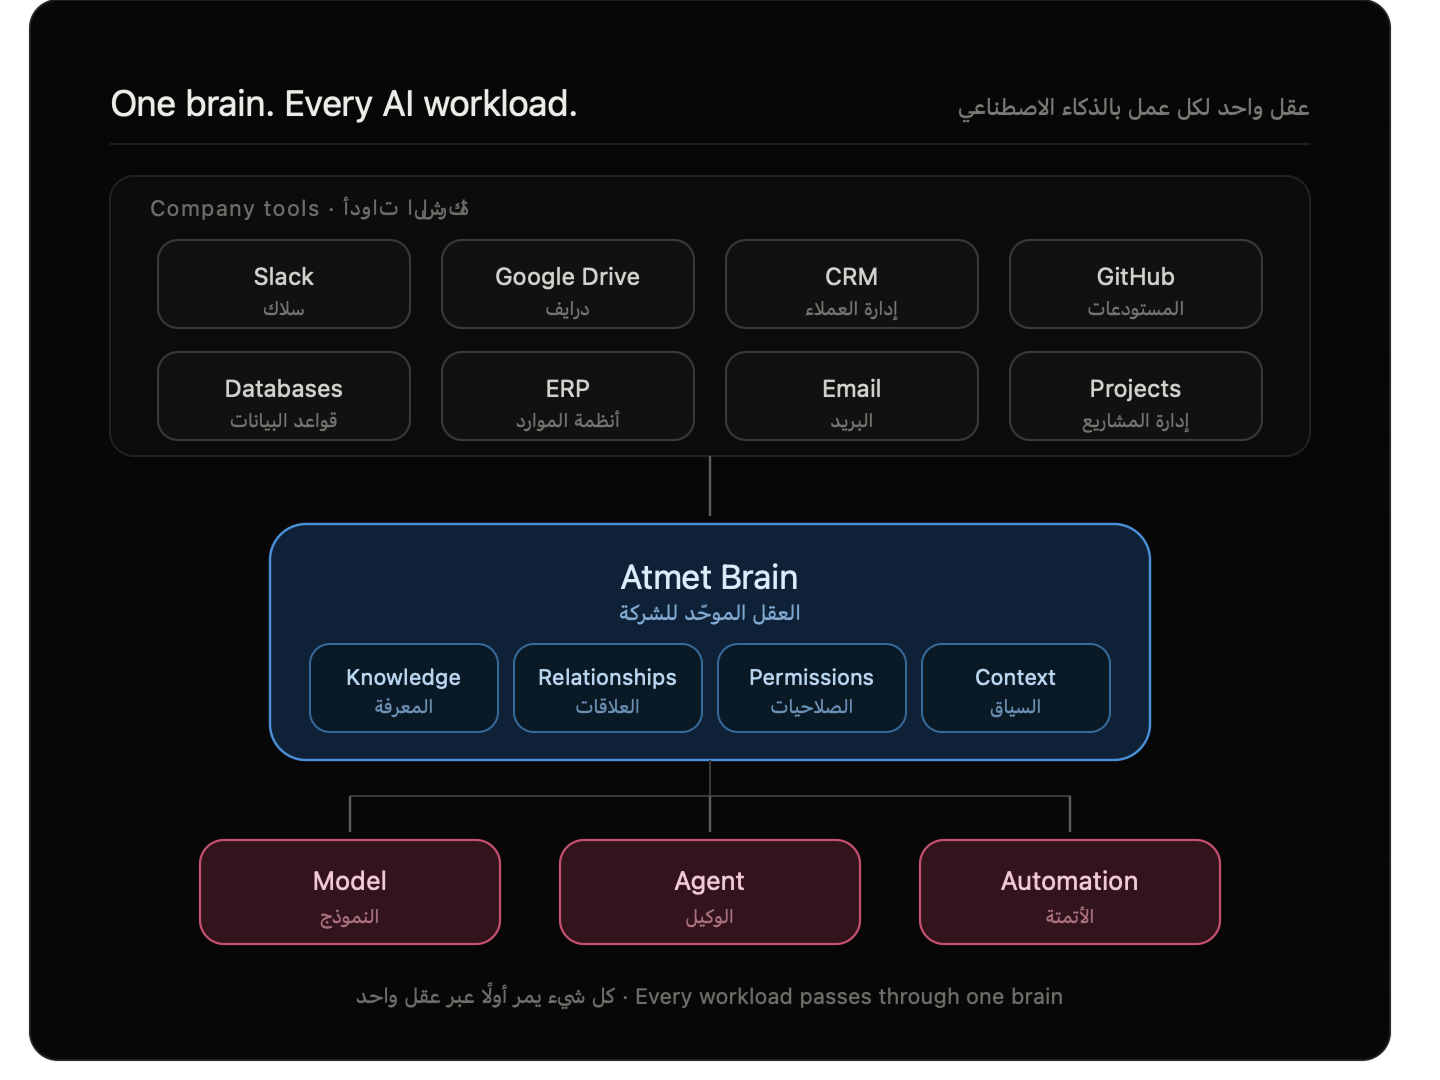
A Slack thread, a CRM record, a project-management task, and a GitHub pull request can all describe the same customer issue. Each source has its own shape, but to the company brain they are parts of one story.
That is why Atmet uses canonical knowledge. Connectors understand their source systems, then normalize content, source, type, date, related projects or customers, people, access rules, and relationships so every approved model or agent can use the knowledge consistently.
Information Alone Was Not Enough
The real value often appears in relationships. A client may connect to a project, a team, a decision, a code change, a later Slack incident, and the engineers who handled it.
A knowledge graph helps the brain understand how company knowledge connects. Some relationships come directly from systems. Others are inferred by AI from content, with confidence and source preserved.
Vector Search Was Strong, But It Saw Only Part of the Picture
Semantic search is excellent when the user uses different words from the source. But exact identifiers, error codes, dates, project scope, recency, permissions, and structured data require other retrieval methods.
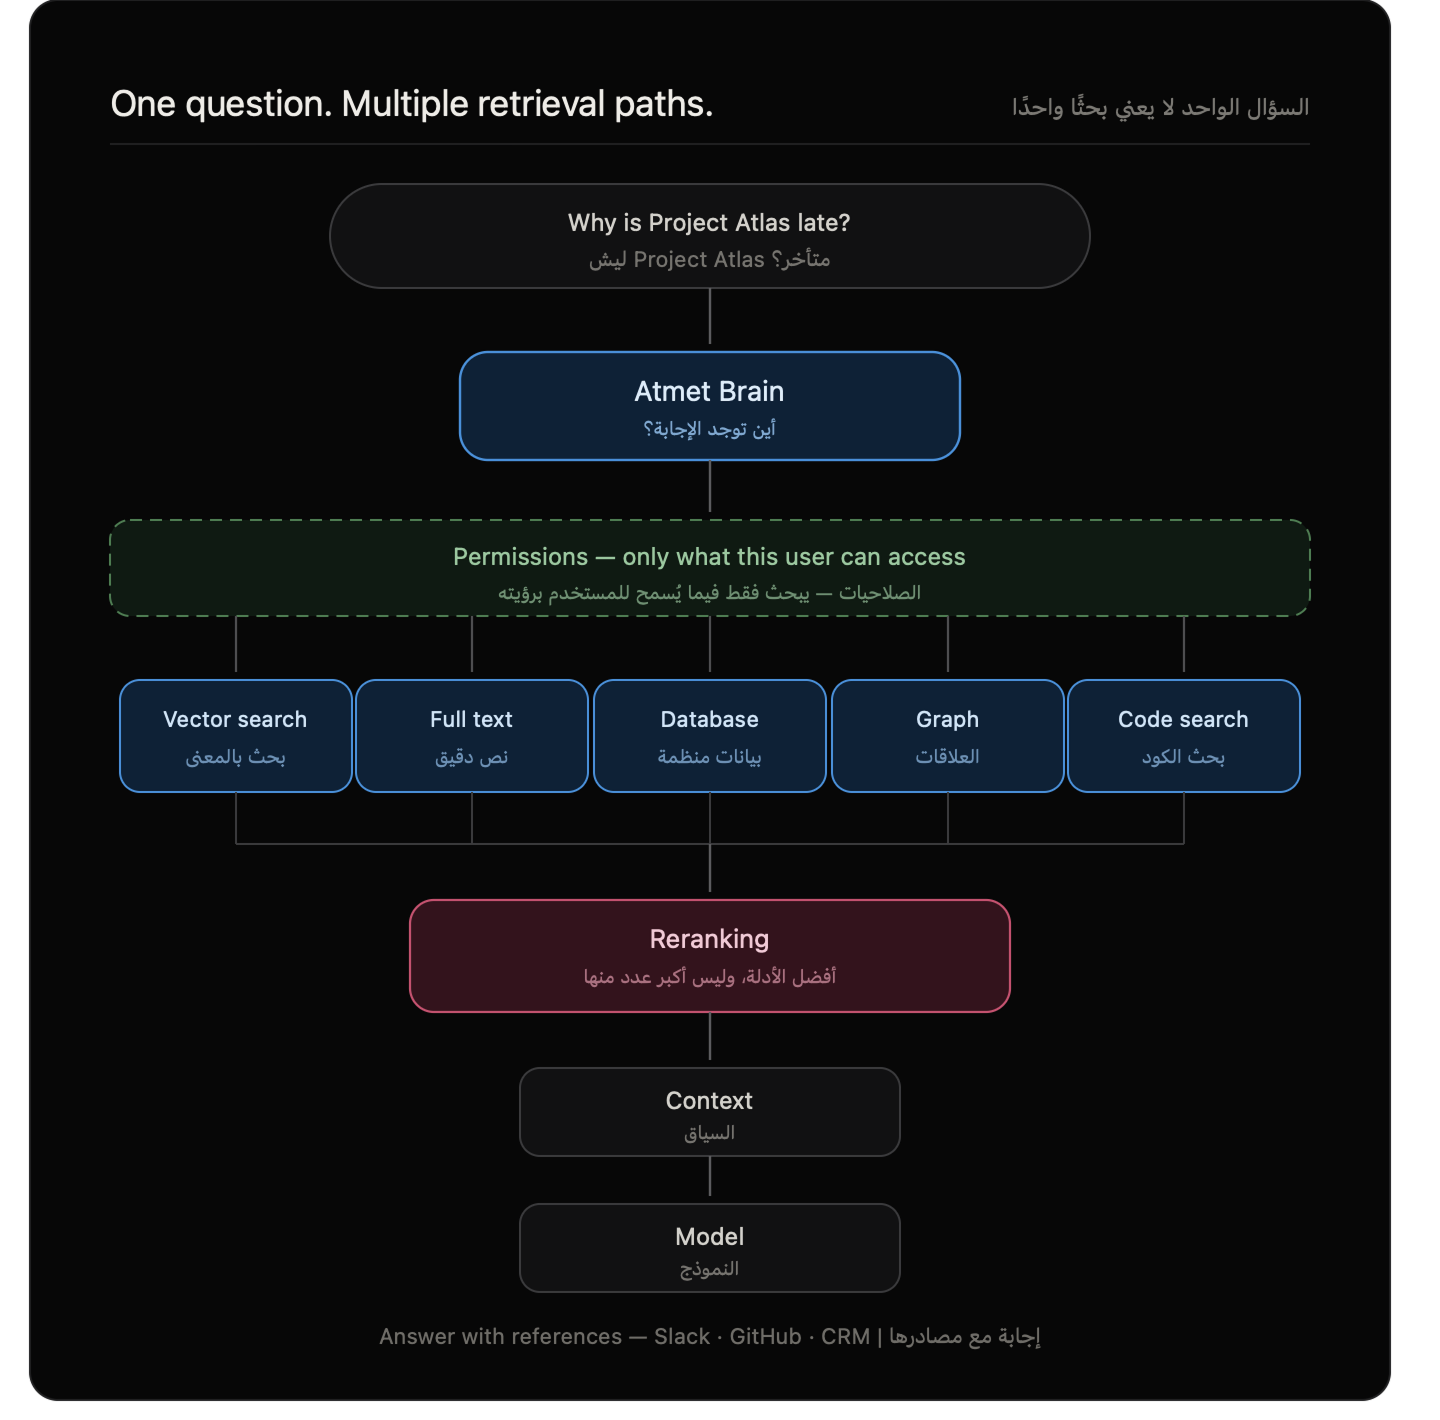
Atmet uses hybrid retrieval: semantic search, full-text search, metadata filters, structured queries, recency, and graph relationships. The brain should not ask every question the same way; it should choose the method that fits the question.
Slack Was One of the Hardest Places to Understand
Documents have titles, sections, and stable context. Slack is different. A thread may begin with “the issue came back,” include logs, explore several theories, and end with one person explaining the real fix.
Treating every message as a separate knowledge chunk loses context. Treating the full thread as one embedding can bury the important signal. Atmet keeps the original conversation while also extracting the issue, systems, root cause, final resolution, participants, and related entities.
Summaries Alone Lose Important Details
A summary helps, but one small message inside a long thread may contain the exact configuration value an engineer needs months later.
So the same conversation can have multiple representations: summary, main question, final answer, related entities, important message groups, and the original text. The design question became: how might a human or agent need to find this knowledge later?
Not Everything Said Inside a Company Should Become Knowledge
A message like “done, thanks” does not have the same value as a message explaining the root cause of a production issue. Index quality starts before a user asks a question.
Atmet looks for signals such as rare terms, error codes, code, final resolutions, longer explanations, and team interaction. If the index fills with low-value content, later retrieval has to repair a problem that should have been prevented earlier.
The Brain Must Move With the Company
The best answer based on outdated information is still a bad answer. Atmet Brain is not a one-time import; it follows source changes continuously.
When Slack threads update, documents change, CRM records move, or code changes, the brain updates the affected knowledge, metadata, relationships, and indexes. It is not an archive of the company. It is a living picture of it.
Structured Data Should Stay Structured
Not everything should be converted into text for embeddings. If a manager asks how many contracts expire this month, the answer belongs in structured data, not paragraphs derived from table rows.
The brain understands different knowledge types and routes questions accordingly: SQL, CRM search, vector search, full text, or graph traversal.
Before Searching, the Brain Must Know Where to Search
Running every retrieval method across every source for every question is expensive and noisy. A contract-renewal question should not search GitHub. An authentication architecture question may need Slack, GitHub, docs, and meeting notes.
Atmet plans lightly before retrieval, using the user identity, permissions, project context, available sources, and the nature of the question to choose where and how to search.
Finding Results Is Easier Than Choosing the Best Ones
After retrieval, many results may appear across sources. The first vector result is not always the best evidence.
Atmet combines signals, deduplicates results, and reranks the strongest evidence against the user question. The goal is not the largest possible context. It is the cleanest, most relevant context.
Sometimes the Right Fact Needs Its Surrounding Context
Chunking helps retrieval, but it can separate a sentence from the heading, thread, class, or neighboring section that makes it true.
After reranking, the brain can expand context: nearby document sections, surrounding Slack messages, or the file around a function. Finding the right sentence is one thing. Understanding it correctly is another.
What an Employee Cannot See, AI Should Not See
Permissions were not an afterthought. If an employee cannot open a finance folder in Google Drive, they should not access it through Atmet by asking differently.
Every knowledge item carries access information, and permissions are applied during retrieval itself. The same question can produce different answers for different people because each person sees a different part of the company.
As the Company Grows, Scope Becomes More Important
Searching everything sounds useful at first. As data grows, it creates noise. Finance does not need engineering repositories for invoice questions, and an engineer working on one service does not need sales presentations in every search.
Atmet organizes knowledge by workspaces, departments, projects, and shared sources so retrieval can narrow scope before search.
Sometimes the Best Answer Is a Person, Not a Document
A mature knowledge graph can identify expertise inside the company. The best answer to “who understands this system?” may be a person who joined the relevant threads, reviewed pull requests, wrote documentation, and attended meetings about the issue.
Not all company knowledge is written. Sometimes the most useful thing Atmet can tell you is who to talk to.
The Difference Between a Knowledge Base and Atmet Brain
If we stopped at search, we would have built enterprise search. Atmet Brain is more than that. It supports answers, agents, and automations before action is taken.
A request like “prepare me for tomorrow’s meeting with X” may need CRM status, recent messages, past meetings, open issues, project status, overdue invoices, and support tickets. The brain provides context; the agent uses it to complete the task.
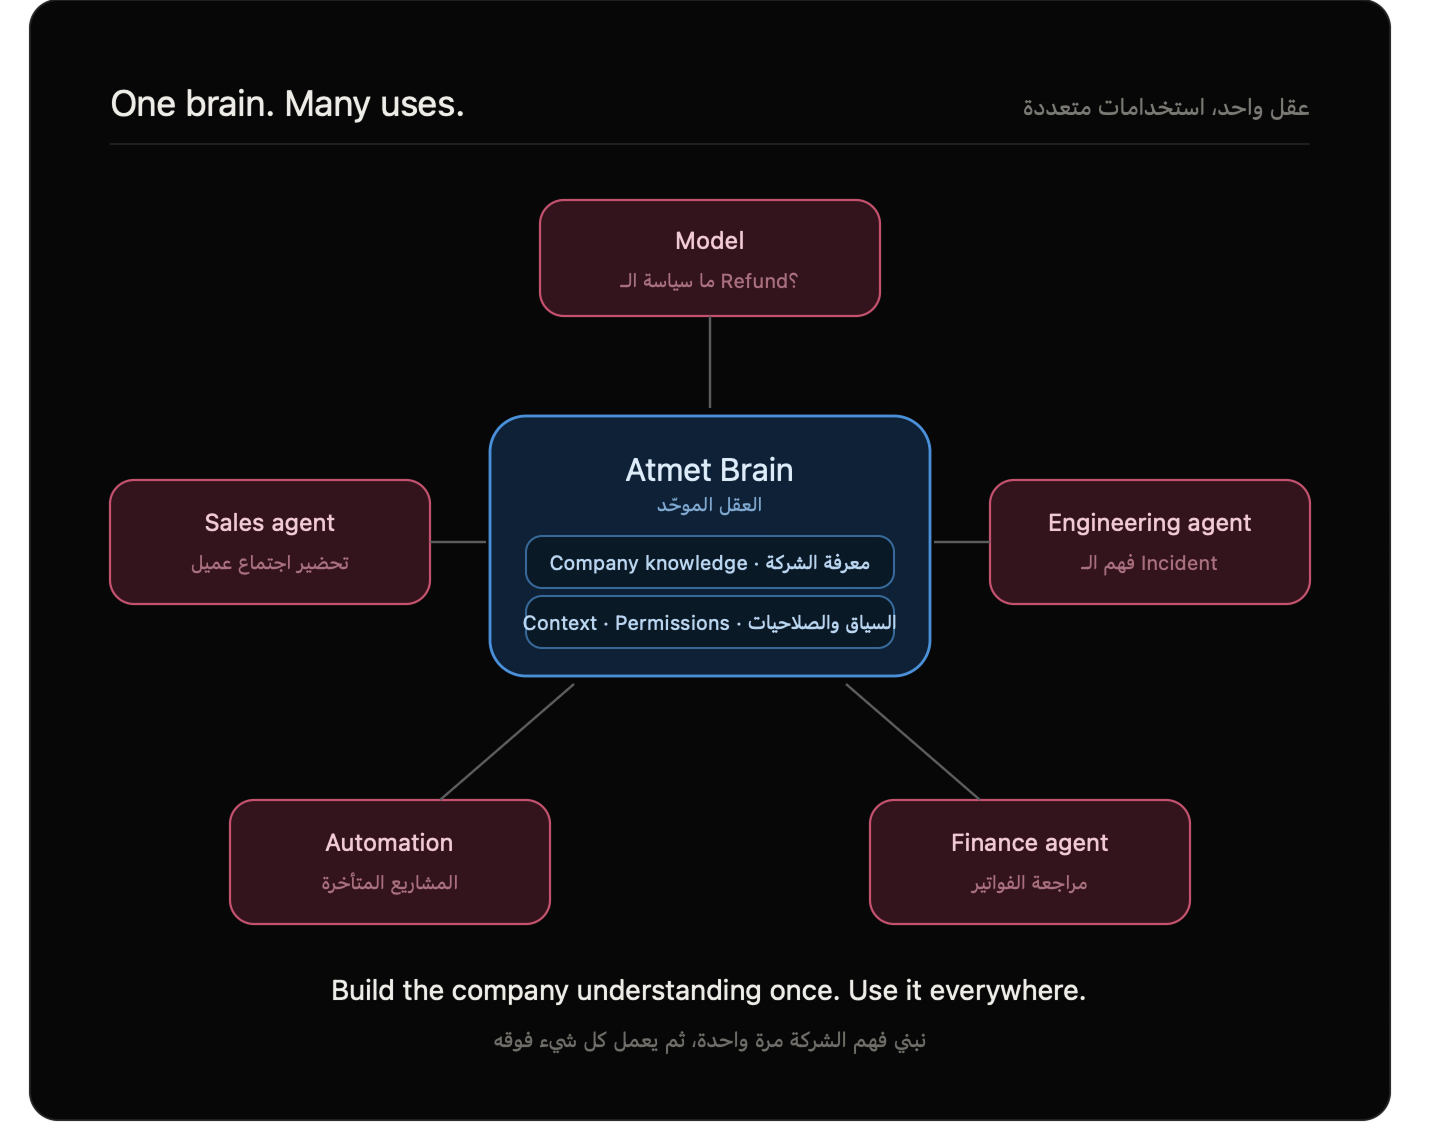
We Do Not Want Every Agent to Learn the Company From Scratch
Without a shared brain, every new agent repeats the same setup: tools, files, project names, people, permissions, and rules.
With Atmet, a new agent enters a company that is already understood. What changes is the agent role: what it can do, what tools it can use, what it can see, and what actions it may take.
The Model Is Not the Company Memory
Atmet Brain was never designed around one model. A user may use OpenAI for one task, Anthropic for another, and a local model for sensitive work.
Company knowledge should not change when the model changes. The brain owns context; the model uses the context it needs.
Even With All This, the Experience Must Stay Simple
Behind one question, the brain may plan retrieval, call sources, merge results, apply permissions, check freshness, rerank evidence, expand context, and send clean context to a model.
The user should not have to see that complexity. They should ask a clear question and receive a clear answer with sources.
What Changed for Client X?
Before the brain, good AI use depended on the person knowing where the files were, which channel mattered, who owned the project, and what to put in the prompt. New employees and new agents lacked that context.
After the brain, there was a shared knowledge layer that understood sources, relationships, and permissions. The company itself became the context.
We Did Not Want the Project to Become a Year-Long Data Migration
Real companies are messy: old files, renamed projects, confusing folders, long conversations, and systems built by different teams over years. Atmet Brain has to work with that reality.
It starts from existing data, connects sources, builds canonical knowledge, extracts relationships, applies permissions, creates indexes, and improves over time. It is not a snapshot taken during setup; it lives with the company.
What Are We Really Building in Atmet?
Running a model, building an agent, connecting an API, and executing automation have all become easier. The harder question remains: what does AI know about the company before it starts working?
Does it know customers, projects, previous decisions, freshness, system relationships, people, permissions, and how to access all of this without being retaught the company every time?
That is why the brain is the Core of Atmet. We do not want to give companies a new AI tool for every problem. We want to build one brain that understands them, then let AI work on top of that understanding.